
AI Training Dataset Market Report Scope & Overview:
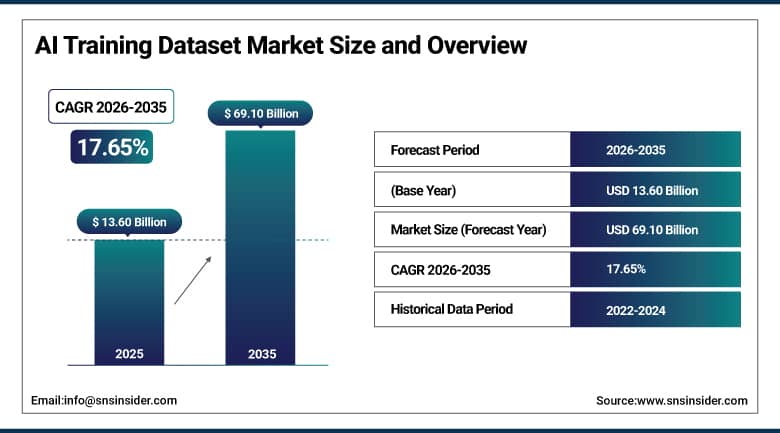
The AI Training Dataset Market was valued at USD 13.60 Billion in 2025 and is expected to reach USD 69.10 Billion by 2035, growing at a CAGR of 17.65% from 2026-2035.
The AI Training Dataset Market is experiencing fast structural transformation due to the fast adoption of large language models, multimodal AI, autonomous driving technologies, medical imaging AI, and enterprise machine learning solutions resulting in a constant need for quality, well-categorized, and frequently updated data sets. Synthetically generated data sets are becoming increasingly popular in this market owing to their ability to solve problems caused by the limited amount of real-life data, its high cost of labeling, and privacy issues, which arise when collecting real data, especially in such domains as autonomous driving, healthcare, and finance. Text and natural language data are the single largest group of data sets because of constantly growing demand for pre-training and instruction-following corpora in the large language model community.
Industry structure shifted decisively in June 2025, when Meta Platforms invested USD 14.3 billion for a 49% stake in Scale AI, valuing the data-labeling company at approximately USD 29 billion in a transaction that did not grant Meta voting control but saw Scale's founder depart to lead a Meta superintelligence research effort. Within days of the announcement, several of Scale's largest customers, including Google, OpenAI, and Microsoft, began reducing or ending their data-labeling engagements with the company over concerns that Meta could gain indirect access to competitors' proprietary training data and model roadmaps, illustrating how vendor neutrality has become a decisive purchasing criterion in a market where AI labs increasingly view their training data pipelines as a core competitive asset rather than a commoditized back-office function.
To Get More Information On AI Training Dataset Market - Request Free Sample Report
AI Training Dataset Market Trends
-
Accelerating adoption of synthetic data generation to address real-world data scarcity and privacy constraints.
-
Growing enterprise concern over data-labeling vendor neutrality following high-profile ownership stake transactions.
-
Rising demand for multimodal datasets supporting cross-modal AI systems spanning text, image, audio, and video.
-
Expanding government and defense procurement of AI training data and model evaluation services.
-
Increasing competitive redistribution of enterprise data-labeling contracts among independent providers.
U.S. AI Training Dataset Market Outlook
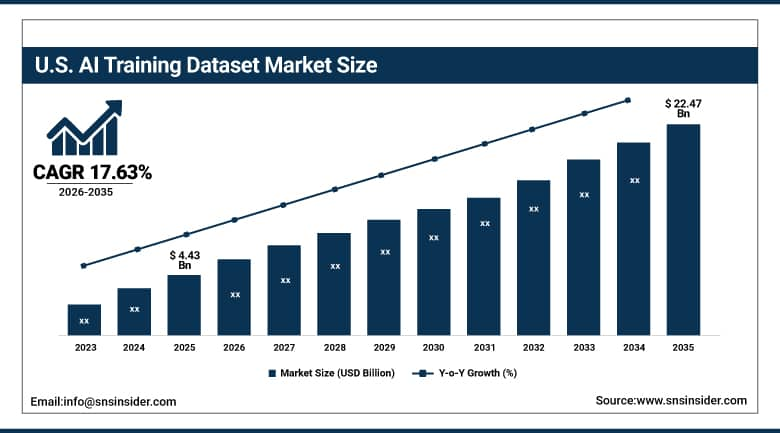
The U.S. AI Training Dataset Market was valued at USD 4.43 Billion in 2025 and is expected to reach USD 22.47 Billion by 2035, growing at a CAGR of 17.63% from 2026-2035.
The U.S. AI Training Dataset Market growth continues to be reinforced by the concentration of the world's largest AI development programs at hyperscalers including Google, Microsoft, Amazon, and Meta, alongside significant pure-play AI labs including OpenAI and Anthropic, all of which require continuous access to high-quality, curated training data. Domestic demand is increasingly extending beyond commercial technology applications into government and defense procurement, as federal agencies pursue AI training data and model evaluation services to support both operational planning and enterprise AI adoption initiatives across multiple agencies.
In March 2025, Scale AI was awarded a prototype contract by the U.S. Defense Innovation Unit for Thunderforge, a program designed to integrate AI into military operational and theater-level planning, extending the company's federal government relationships beyond its earlier data-labeling contracts. The award illustrates how domestic training data providers are increasingly diversifying their revenue base toward government and defense customers, a segment that has continued to expand its engagement with data providers even as several large commercial technology clients reduced their contracts following industry ownership realignments during 2025.
AI Training Dataset Market Segment Analysis
-
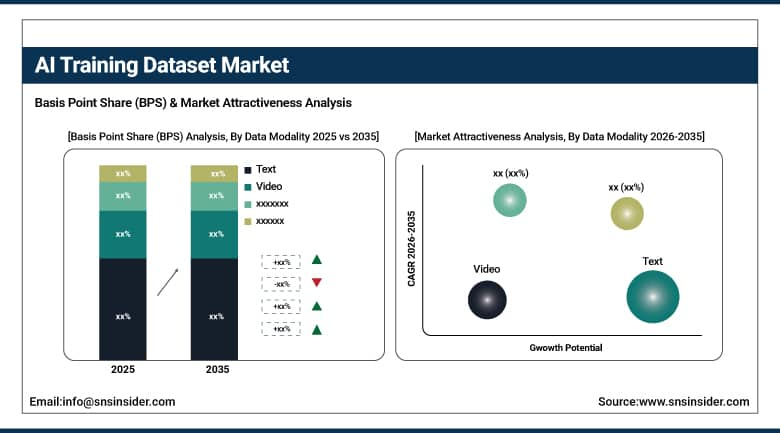
By Data Modality, the Text segment dominated the AI Training Dataset Market with approximately 34.60% share in 2025, while the Video segment is the fastest growing with a CAGR of approximately 32.75%.
-
By Annotation Type, the Image Annotation segment dominated the AI Training Dataset Market with approximately 41.85% share in 2025, while the Video Annotation segment is the fastest growing with a CAGR of approximately 24.60%.
-
By Vertical, the IT & Telecommunications segment dominated the AI Training Dataset Market with approximately 29.75% share in 2025, while the Healthcare segment is the fastest growing with a CAGR of approximately 26.85%.
By Data Modality, Text dominates, and Video grows fastest
The text segment still dominates the AI Training Data Segment market due to the voracious appetite that exists in the large language model community for both pre-trained textual corpuses as well as text that is capable of instruction following. The relative maturity of the process of sourcing, licensing, and annotating textual data sets is an advantage to this segment.
The video is the fastest-growing modality type in the AI Training Dataset Market owing to rising demand for computer vision, autonomous driving, surveillance, robotics, and video-based generative AI solutions. The development of video datasets involves significant effort in frame-level labeling and context labeling. Increasing demand for multimodal AI and video analytics technologies is contributing to growth in the segment, along with advancements in automated annotation and synthetic video creation.
By Annotation Type, Image Annotation dominates, and Video Annotation grows fastest
Image Annotation remains the dominant annotation-type segment, characterized by the capital intensity of computer vision training data production and its broad application across autonomous vehicles, medical imaging, retail, and surveillance use cases that have matured over multiple model development cycles.
Video Annotation is emerging as the fastest-growing annotation-type segment, driven by expanding computer vision applications in autonomous driving and robotics that require temporally continuous, frame-by-frame labeled data. As autonomous system developers prioritize richer scene understanding, this segment focuses strongly on scalable annotation pipelines capable of processing substantially larger data volumes than static image labeling requires.
By Vertical, IT & Telecommunications dominates, and Healthcare grows fastest
IT & Telecommunications remains the dominant vertical segment, characterized by the sector's position at the center of foundation model and enterprise AI platform development, generating the broadest and highest-volume demand for training data across nearly every data type and annotation category.
In the same way, Healthcare has become the fastest growing vertical industry sector, powered by increasing use cases of AI such as diagnosis, health management, VR-based treatment, wearables, and voice-based symptom checkers; all of which need huge volumes of curated data to achieve accurate results. With increasing emphasis on AI-powered accurate diagnosis in healthcare industry, the focus of this vertical industry lies on high-quality validated data for imaging and clinical text.
Regional Analysis
|
Region |
Major Country |
Share within Region, 2025 (%) |
|---|---|---|
|
North America |
United States |
84.30 |
|
Europe |
Germany |
28.75 |
|
Asia Pacific |
China |
44.60 |
|
Middle East & Africa |
United Arab Emirates |
36.90 |
|
Latin America |
Brazil |
41.75 |
North America AI Training Dataset Market Insights
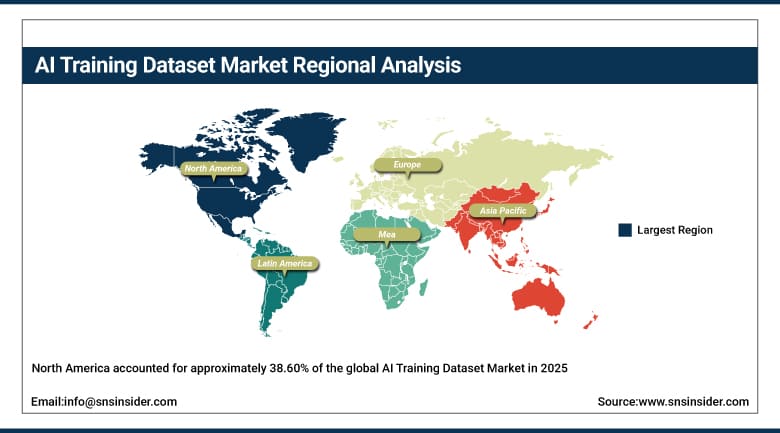
North America accounted for approximately 38.60% of the global AI Training Dataset Market in 2025, remaining the largest regional market on the strength of the concentration of the world's largest AI development programs at hyperscalers including Google, Microsoft, Amazon, and Meta, alongside significant pure-play AI labs including OpenAI and Anthropic. The United States dominates regional demand, home to the majority of the sector's largest data-labeling and annotation providers, including Scale AI, Appen, and Innodata.
The region's competitive landscape shifted meaningfully following Meta's June 2025 investment in Scale AI, which prompted several large technology clients to redistribute data-labeling contracts toward independent providers including Turing, Surge AI, and Mercor. Canada contributes additional regional demand through its own growing artificial intelligence research and enterprise AI adoption activity.
Get Customized Report as Per Your Business Requirement - Enquiry Now
Asia Pacific AI Training Dataset Market Insights
Asia Pacific region is anticipated to grow at a CAGR of about 30.85% between 2026 and 2035, the highest compared to all other regions, attributed to the huge mobile user community and strategic initiatives adopted by government in adopting AI in China and India. The rapid expansion of the Chinese domestic AI development segment, due to the presence of hyperscale tech firms and specialized data annotation service providers, is fueling regional demand for datasets.
However, with India having an ample amount of annotators who speak fluent English, the country still remains a major player in the outsourcing of data labeling services. In addition to this, Japan and South Korea also add some demand in the region owing to the presence of their robotics industry and the development of self-driving cars.
Europe AI Training Dataset Market Insights
Europe represents a significant AI Training Dataset Market, shaped by the EU AI Act's data governance and transparency requirements, which are influencing how training datasets are sourced, documented, and audited across the region. Germany leads regional demand, supported by its concentration of automotive and industrial AI development requiring substantial annotated sensor and computer vision data.
The French and British nations provide a significant source of regional demand by virtue of their own AI research facilities and increasing AI adoption in businesses, while future EU regulatory focus on data provenance and privacy compliance will likely determine future training data acquisition methods over the forecast period.
MEA & Latin America AI Training Dataset Market Insights
The Middle East & Africa AI Training Dataset Market is expanding as Gulf Cooperation Council states invest heavily in national AI strategies and sovereign AI infrastructure, with the United Arab Emirates driving regional demand through substantial government-backed AI research and development investment.
Latin America's AI training dataset activity remains at an earlier stage of development, with Brazil representing the region's primary point of engagement given its growing technology sector and expanding enterprise AI adoption across financial services and retail applications.
Growth Drivers: Foundation Model Development and Synthetic Data Adoption
Rapid development and adoption of large language models, multimodal artificial intelligence systems, and enterprise machine learning applications continue to be the key growth drivers for the AI Training Dataset Market since newer versions of these models need bigger and better training datasets in order to perform better than their predecessors.
Growing synthetic data adoption is reinforcing this driver by addressing real-world data scarcity, high labeling costs, and privacy constraints that limit access to sensitive or rare-event data in domains such as autonomous driving, healthcare, and finance. This capability is directly expanding the addressable training data supply available to model developers without requiring proportional increases in manual data collection effort.
Restraints: Data Privacy Concerns and Vendor Neutrality Risk
Data privacy concerns keep hindering the accessibility and usability of datasets for training purposes, as companies are under increasing pressure to address their regulation on the origin and source of the data used in the training of AI commercial products.
Vendor neutrality risk has emerged as a significant restraint following Meta's 2025 investment in Scale AI, which prompted several major technology clients to reduce their engagements over concerns that a competitor's ownership stake could compromise the confidentiality of proprietary training data and model development roadmaps shared with a shared data provider.
Opportunities: Government AI Procurement and Multimodal Data Expansion
Growing government and defense procurement of AI training data and model evaluation services presents a significant opportunity for providers able to meet the security clearance and compliance requirements that public-sector AI contracts demand, a segment that has continued expanding even as some commercial technology engagements have contracted.
The continued expansion of multimodal AI development presents a further opportunity for data providers capable of delivering synchronized, cross-referenced datasets spanning text, image, audio, and video simultaneously. Providers successfully building multimodal data collection and annotation capability are positioned to capture premium pricing as foundation model developers increasingly prioritize generalized, cross-modal reasoning capability over single-purpose models.
Recent Developments:
-
2026: Snorkel AI, Princeton, and UW–Madison researchers released Senior SWE-bench, a new benchmark designed to evaluate AI agents on complex software-engineering tasks and support development of higher-quality training and evaluation data.
-
2026: Defined.ai expanded its Physical AI data offering with multimodal robotics datasets and customized multi-sensor data collection covering visual, LiDAR, radar, motion-capture, force/torque, and human-demonstration data.
-
2026: LXT Inc. introduced Crowd-as-a-Service (CaaS) with API access to a global network of more than 10 million contributors, allowing AI teams to integrate data-collection and annotation workflows directly into their systems.
AI Training Dataset Market Key Players are:
-
Scale AI, Inc.
-
Innodata Inc.
-
TransPerfect (DataForce)
-
Turing
-
Surge AI
-
Mercor
-
Snorkel AI, Inc.
-
Labelbox, Inc.
-
Gretel.ai
-
Defined.ai
-
Speechocean
-
Datatang
-
Shaip
-
LXT Inc.
-
iMerit Technology Services Pvt. Ltd.
-
Sama
-
TELUS International
-
Hugging Face, Inc.
AI Training Dataset Market Report Scope :
| Report Attributes | Details |
|---|---|
| Market Size in 2025 | USD 13.60 Billion |
| Market Size by 2035 | USD 69.10 Billion |
| CAGR | CAGR of 17.65% From 2026 to 2035 |
| Base Year | 2025 |
| Forecast Period | 2026-2035 |
| Historical Data | 2022-2024 |
| Report Scope & Coverage | Market Size, Segments Analysis, Competitive Landscape, Regional Analysis, DROC & SWOT Analysis, Forecast Outlook |
| Key Segments | • By Data Modality (Text, Image, Video, Audio, Multimodal, Others) • By Annotation Type (Image Annotation, Text Annotation, Audio Annotation, Video Annotation, Multimodal Annotation, Synthetic / AI-Assisted Annotation, Others) • By Vertical (IT & Telecommunications, Automotive, Healthcare, BFSI, Retail & E-commerce, Government, Others) |
| Regional Analysis/Coverage | North America (US, Canada), Europe (Germany, UK, France, Italy, Spain, Russia, Poland, Rest of Europe), Asia Pacific (China, India, Japan, South Korea, Australia, ASEAN Countries, Rest of Asia Pacific), Middle East & Africa (UAE, Saudi Arabia, Qatar, South Africa, Rest of Middle East & Africa), Latin America (Brazil, Argentina, Mexico, Colombia, Rest of Latin America). |
| Company Profiles | Scale AI, Inc., Appen Limited, Innodata Inc., TransPerfect (DataForce), Turing, Surge AI, Mercor, Snorkel AI, Inc., Labelbox, Inc., Gretel.ai, Mostly AI, Defined.ai, Speechocean, Datatang, Shaip, LXT Inc., iMerit Technology Services Pvt. Ltd., Sama, TELUS International, Hugging Face, Inc. |

Frequently Asked Questions
Key players in the AI Training Dataset Market include Scale AI, Inc., Appen Limited, Innodata Inc., TransPerfect (DataForce), and Turing, among others.
Key opportunities lie in government and defense AI procurement contracts, and in multimodal data collection and annotation capability serving foundation model developers.
The accelerating deployment of large language models and multimodal AI systems, combined with growing synthetic data adoption addressing real-world data scarcity, is the major growth factor.
By Data Modality, the Text segment dominated the AI Training Dataset Market with approximately 34.60% share in 2025.
North America dominated the AI Training Dataset Market with approximately 38.60% share in 2025, supported by the concentration of the world's largest AI development programs.
